Retrieval-Augmented Generation (RAG): A Short Introduction
 By Suraj Rao4 min read
Discover RAG in AI: a method enhancing data richness and outcomes by linking AI models to vast data sources.
Introduction
In the evolving field of natural language processing (NLP), large language models (LLMs) such as GPT-4 have become increasingly powerful at generating human-like text. Despite their remarkable capabilities, these models have inherent limitations, particularly when it comes to retrieving or reasoning about specific, up-to-date, or domain-specific information. This is where Retrieval-Augmented Generation (RAG) comes into play, bridging the gap between generative language models and retrieval systems.
Explore the core of RAG in AI: a methodology that enhances data accessibility and enriches outcomes by linking AI models to expansive data sources.
RAG combines the generative prowess of LLMs with the precision of information retrieval systems, enabling the generation of accurate, contextually relevant, and grounded responses. This blog post delves into the basics of RAG, its architecture, working principles, applications, and implementation details, complete with Python code snippets to help you understand and implement RAG in your own projects.
What is Retrieval-Augmented Generation (RAG)?
RAG is an approach to NLP that integrates information retrieval into the text generation process. Instead of relying solely on the pre-trained knowledge of a language model, RAG retrieves relevant documents or knowledge snippets from an external corpus and uses them to guide the generation of responses.
This technique is particularly valuable in applications requiring domain-specific expertise, such as customer support, academic research, or medical diagnosis, where relying solely on a model's training data can lead to outdated or inaccurate results.
Architecture of RAG
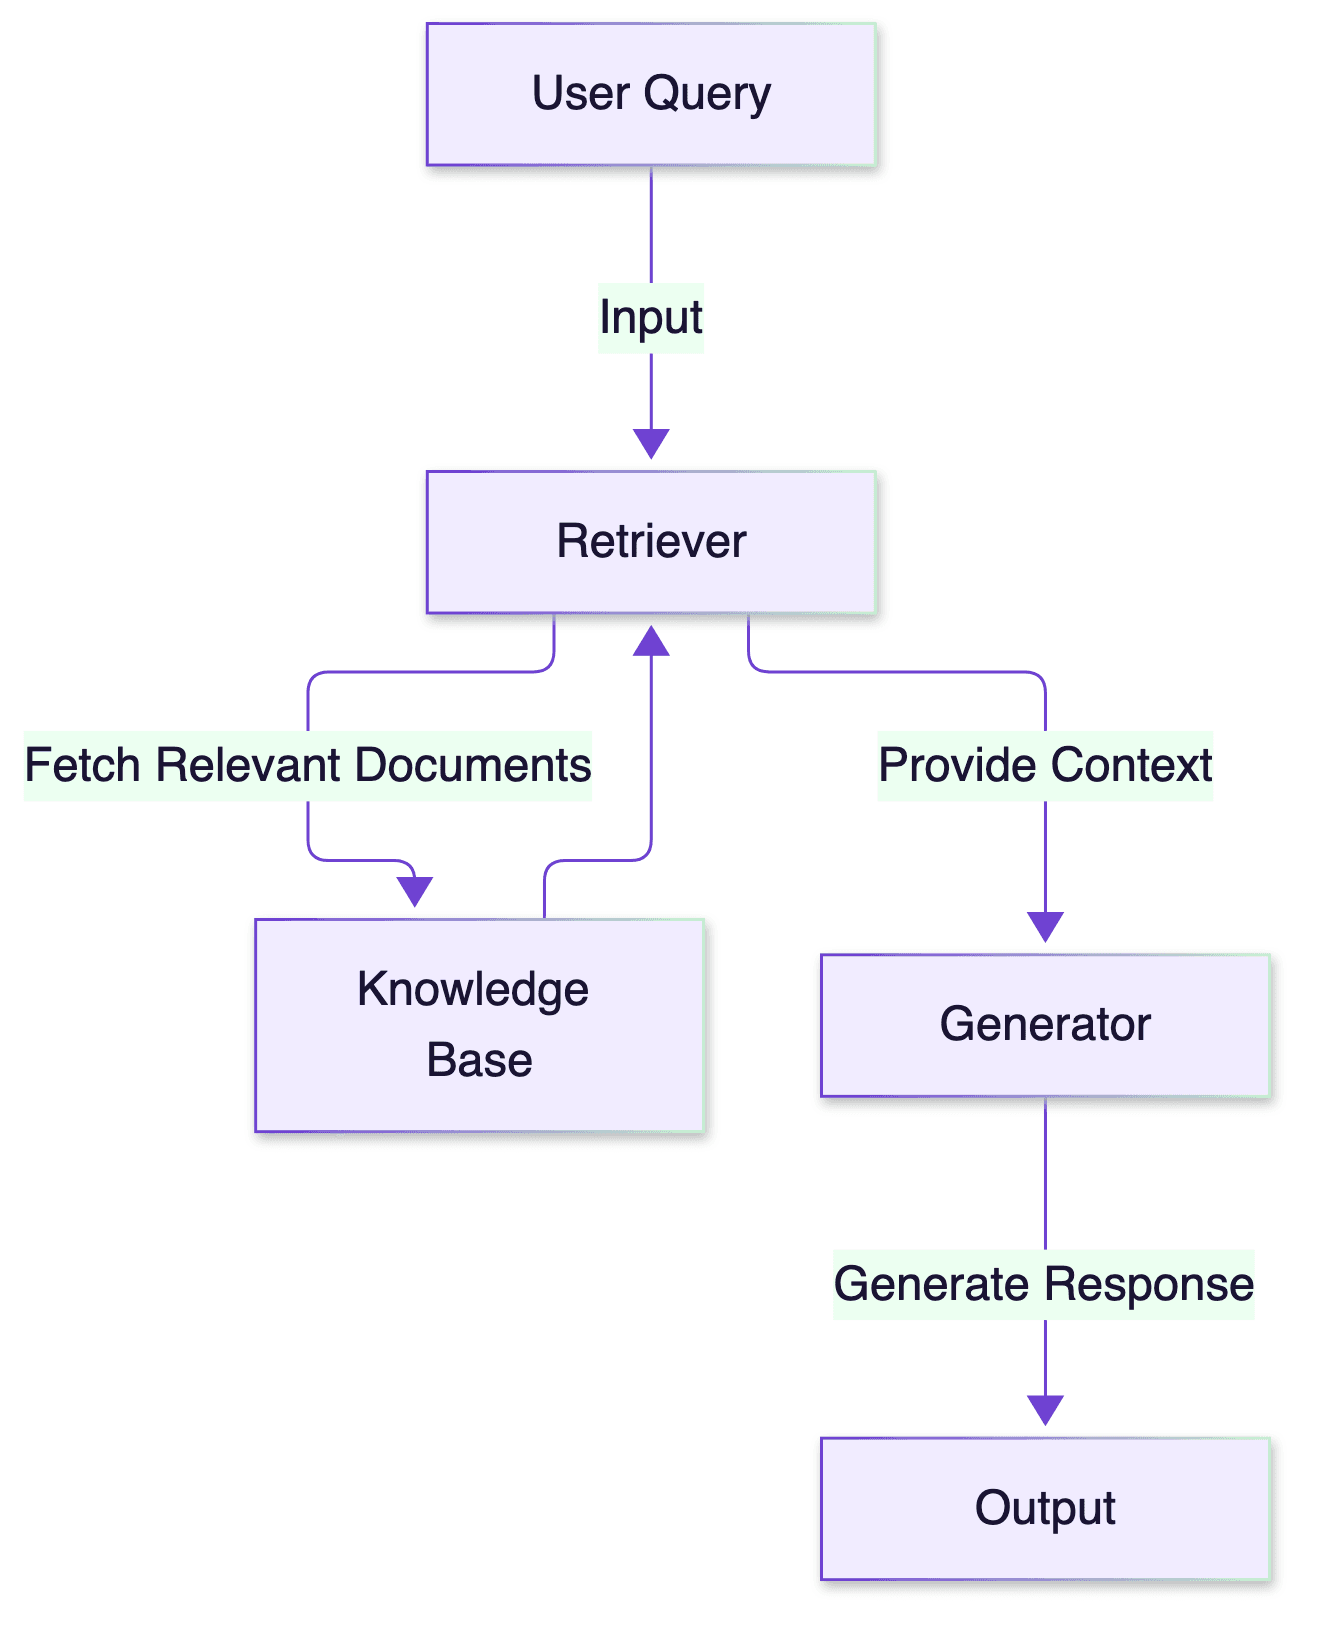
The RAG framework typically involves two main components:
-
Retriever: This component retrieves relevant documents or information from an external corpus based on the input query. Common retrievers include:
-
Sparse vector retrievers (e.g., BM25)
-
Dense vector retrievers (e.g., embeddings using Sentence-BERT or FAISS)
-
-
Generator: A language model (e.g., GPT, BERT-based models) that uses the retrieved information as additional context to generate responses.
How RAG Works

-
Input Query: A user provides a query or prompt.
-
Document Retrieval: The retriever searches an external knowledge base or corpus to find documents relevant to the query.
-
Contextual Generation: The generator uses the retrieved documents along with the original query to generate a coherent and informed response.
-
Output: The model outputs a response that incorporates the retrieved information.
This flow ensures that the model's responses are both creative and grounded in factual, up-to-date information.
Applications of RAG
RAG has a wide range of applications, including:
-
Customer Support: Providing accurate and quick responses to user queries by retrieving company-specific FAQs or documentation.
-
Academic Research: Assisting researchers by summarizing papers or articles related to a specific topic.
-
Healthcare: Supporting medical professionals by retrieving information from medical literature.
-
E-commerce: Enhancing product search and recommendation systems.
Implementing RAG in Python
Below is a step-by-step guide to implementing a simple RAG system using Python. We’ll use libraries like Hugging Face Transformers and FAISS for the retriever and generator components.
1. Setting up the environment
pip install transformers faiss-cpu datasets2. Preparing the Corpus
Load a sample corpus (e.g., Wikipedia articles):
from datasets import load_dataset

# Load a sample dataset
data = load_dataset("wikipedia", "20220301.simple")

# Extract relevant fields (e.g., title and text)
corpus = [doc["text"] for doc in data["train"]]
3. Creating the Retriever
Use FAISS to build a dense vector index for the corpus:
from sentence_transformers import SentenceTransformer
import faiss

# Load a pre-trained Sentence Transformer model
embedding_model = SentenceTransformer('all-MiniLM-L6-v2')

# Compute embeddings for the corpus
corpus_embeddings = embedding_model.encode(corpus, convert_to_tensor=False)

# Build the FAISS index
index = faiss.IndexFlatL2(corpus_embeddings.shape[1])
index.add(corpus_embeddings)

print(f"Indexed {len(corpus)} documents.")
4. Querying the Retriever
Given a query, retrieve the top-k relevant documents:
query = "What are the benefits of Retrieval-Augmented Generation?"
query_embedding = embedding_model.encode([query])

# Retrieve the top 3 documents
_, top_k_indices = index.search(query_embedding, k=3)
retrieved_docs = [corpus[i] for i in top_k_indices[0]]

print("Top retrieved documents:")
for doc in retrieved_docs:
    print(doc[:200], "...")
5. Using the Generator
Leverage a pre-trained language model (e.g., GPT) to generate a response:
from transformers import AutoTokenizer, AutoModelForSeq2SeqLM

# Load the generator model and tokenizer
generator_model = AutoModelForSeq2SeqLM.from_pretrained("facebook/bart-large-cnn")
generator_tokenizer = AutoTokenizer.from_pretrained("facebook/bart-large-cnn")

# Combine retrieved docs and query as input
input_text = query + "\n" + "\n".join(retrieved_docs)
inputs = generator_tokenizer.encode(input_text, return_tensors="pt", max_length=1024, truncation=True)

# Generate a response
outputs = generator_model.generate(inputs, max_length=200, num_beams=4, early_stopping=True)
response = generator_tokenizer.decode(outputs[0], skip_special_tokens=True)

print("Generated Response:")
print(response)
Advantages of RAG
-
Improved Accuracy:RAG ensures responses are grounded in factual, up-to-date information. -
Domain Adaptability:By using a custom corpus, RAG can be tailored to specific domains. -
Scalability:RAG systems can scale to vast corpora with the help of efficient retrievers like FAISS.
Conclusion
Retrieval-Augmented Generation represents a significant step forward in NLP, addressing the limitations of generative models by grounding their outputs in real-world information. By combining retrieval systems with language models, RAG opens up new possibilities for creating intelligent, domain-specific applications. With tools like Hugging Face Transformers and FAISS, implementing RAG has become accessible to developers, making it an essential technique for the future of AI-powered applications.
Category: AI
Suraj Rao
Suraj Rao is the founder of Tristiks, the team behind Tristiks Grow and its desktop time tracker OneTrack. He writes about time tracking, client work and getting paid, and about DevOps, cloud and AI from years of building software.